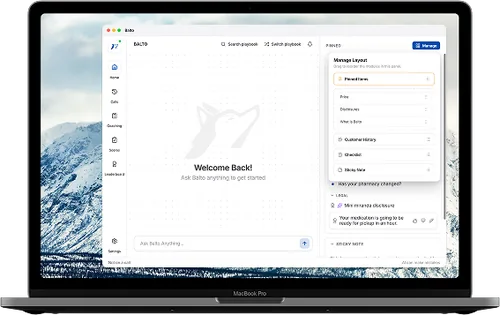
Score every call. See the evidence behind every score.
Balto scores every call in seconds not hours, helps you build your scorecard, and lets you go from any score straight to the call behind it.
Every interaction gets scored
Not a two percent sample. Every call is scored against your scorecard, so your QA data reflects what is actually happening across the contact center.
Get the score while the call is still fresh
Calls are scored within seconds of hangup, so managers can review and coach without waiting for a QA queue to clear. Every call is scored, not just a sample.
Sample data.
Build your scorecard from the way you actually run your business
Give Balto your playbook, policies, or existing QA criteria. It builds the scorecard for you, including criteria, weights, and auto fails. Review the setup, make your changes, and publish.
After launch, Kodi reads your calls and tells you when the scorecard needs to change.
Every score is backed by the call
Click a score to see the calls behind it. Go straight to the agent, the conversation, and the exact part of the scorecard being evaluated, with the recording and transcript in the same view.
ads_clickClick a score in the tableSet your own pass mark
Drag it and see how many calls move, before you change anything for real.
Build the dashboard you actually read
Every component here drags into place on yours.
What else comes with it
Streak alerts
Three misses on the same criterion raises the agent.
Dispute tracking
Disputes against overturns, so leniency stays visible.
Agent and tag views
The same components scoped to one person or one site.
Scorecard upkeep
Kodi drafts the edit when your calls change. You approve it.
Same platform as guidance
Agents get live help on the criteria you score them on.
CSV everywhere
Including the filtered set behind any drill-in.
Explore Balto's AI workforce
Agent Assist
Real-time guidance, knowledge base answers, and objection handling while the conversation is live.
DiscoverInsights
Ask what is driving contacts in plain language and get an answer drawn from every conversation.
DiscoverCoaching
Balto finds the coachable moments in each agent's own conversations and builds the session for you.
DiscoverNotes
Summaries and CRM fields written automatically, so after-call work stops eating into handle time.
DiscoverAI Agents
Togo handles routine conversations end to end, then hands a person the full context when one is needed.
DiscoverOmnichannel AI
Voice, email, chat and SMS stored and scored in one platform, so quality and coaching stay consistent across every channel.
DiscoverFAQs
Call center quality assurance software checks what happened on a call against the standards a business sets, then turns the result into something a supervisor can act on. Traditionally an analyst listened to a handful of calls a week and hoped the sample was representative; at two percent coverage, most of what an agent does is never looked at. Balto scores every call instead, on a scorecard built from your own playbook, and every number opens the conversations behind it.
Scoring starts when the call ends, and the result is normally there before the agent finishes wrap-up. There is no overnight batch and no reviewer to wait for, because Balto scores every call instead of picking a sample. That is what makes coaching the same shift possible.
No. Describe what you score on in plain English, or hand over the playbook and QA form you already use. Balto drafts the criteria with suggested weights and auto-fail flags. You change any wording, set the weights, and publish. Most teams have a working scorecard the same day.
Kodi keeps reading your calls. When something starts coming up that the scorecard has no criterion for, or a criterion is worded too loosely to score the same way twice, it brings you the change already written. Nothing is applied until you approve it.
Yes, from anywhere on the dashboard. Every bar, cell and row opens the calls behind it, already filtered to the criterion and the agent you clicked. You get the recording, the transcript, the criterion that failed and the moment it failed, so a disputed score gets settled by listening.
Yes. Open the review, mark the criterion Pass, Fail or N/A yourself, and your answer is the one that counts. Balto tracks how often scores are disputed and how often supervisors overturn them, so you can see whether the model is drifting or a team is marking too kindly.
No. Flagged means one criterion was missed. The call can still pass overall, which is why calls with failed criteria is tracked separately from pass rate. The gap between those two numbers is usually where the coaching is.
Two reasons, in order. Early on the scoring itself gets more accurate as prompts are tuned from calibration feedback, which is the system improving rather than the agents. Once scoring settles, what you are looking at is real agent improvement.
Yes. Screens show the first 200 rows to stay readable, and the full dataset exports to CSV from any widget, including the filtered set behind a drill-in.
See your own scorecards on it.
We'll load your scorecards into the dashboard and walk your QA leads through the first coaching session it produces.
Book by phone
+1 (405) 864-4645Call and speak directly with our AI agent to schedule your demo, available 24/7, no wait time.
Call now- Give agents the right answer in real time, pulled straight from your own knowledge base.
- Coach faster. Balto spots who needs it, does the prep, and takes you right to the coachable moments.
- See the trends driving your business out of the box, no setup required.
- QA every conversation automatically, so all that’s left is a quick review before it reaches leadership.